GGUF is the model file format used for local LLM inference with llama.cpp and the tools built on it in 2026. The older GGML file format is retired, although the ggml tensor library itself is still actively developed.
Key facts
Updated 2026-09-24: added Key facts, question headings with direct answers, and an FAQ built from the questions Google shows for this topic.
What is the current state of GGUF and GGML in 2026?
GGUF replaced the old GGML file format in August 2023, when llama.cpp merged the GGUF pull request ↗ as a breaking change. Current local inference tools load GGUF, not legacy GGML .bin files. User discussions now center on GGUF quantization levels such as Q4_K_M and Q5_K_M.
Why GGML Became Obsolete
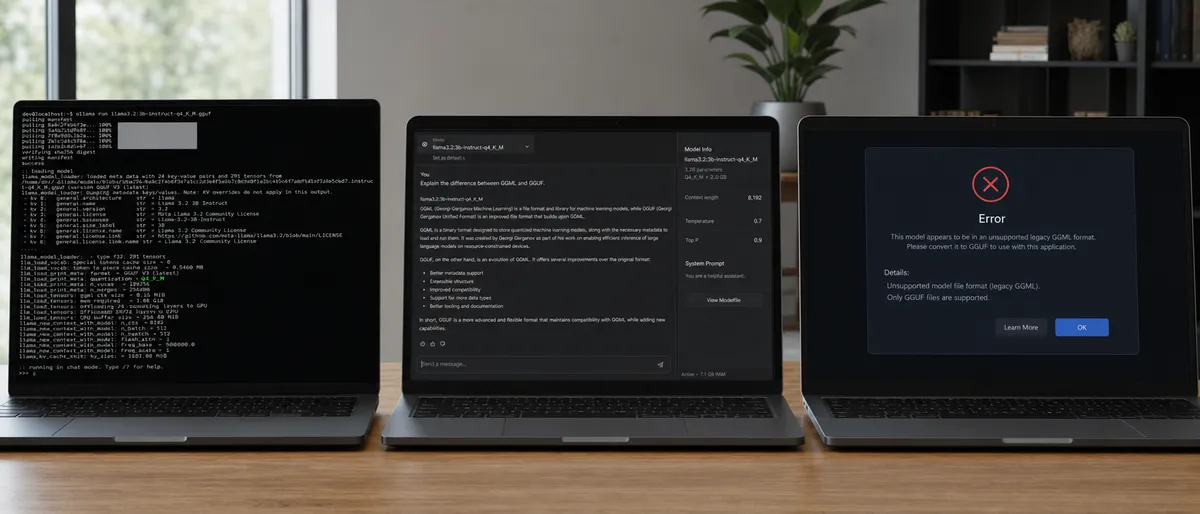
"GGML" names two things: the ggml tensor library that powers llama.cpp, and the early model file format that used it. The library is still maintained in the ggml-org/ggml repository ↗; only the file format is obsolete. According to the GGUF specification ↗, GGUF is the successor to the GGML, GGMF and GGJT formats. The old formats did not identify the model architecture, and adding a new hyperparameter was a breaking change. llama.cpp stopped loading the old files when GGUF was merged on August 21, 2023. GPT4All dropped .bin GGML models in version 2.5.0 in October 2023. Ollama, LM Studio and GPT4All all load GGUF files today. Legacy GGML files produce load errors in these tools. In February 2026, ggml.ai, the company behind ggml and llama.cpp, joined Hugging Face ↗; both projects remain open source under the MIT license. All current local deployments in these tools use GGUF.
GGUF as the Unified Standard
GGUF replaced GGML as the single binary container. The format stores metadata, tokenizer information and tensor data in one file, using a typed key-value structure for metadata. llama.cpp produces new GGUF files with the convert_hf_to_gguf.py script. Hugging Face supports GGUF on the Hub and shows file metadata in its viewer. Direct GGUF vs GGML model comparisons appear mostly in historical threads from 2023. Ollama can import GGUF files through a Modelfile. LM Studio lists GGUF models by size and quantization. llama-cpp-python loads GGUF models through bindings to the llama.cpp library. For Llama 3.1 8B, the llama.cpp quantize README ↗ lists Q4_K_M at about 4.89 bits per weight, Q5_K_M at about 5.70, and Q6_K at about 6.56. Community discussions in 2025 and 2026 focus on GGUF quantization levels and mention GGML mainly as a legacy format.
llama.cpp, Ollama, LM Studio, GPT4All and llama-cpp-python are the common GGUF runtimes, and all five are free to run locally. llama.cpp gives the most control over quantization and GPU offload, Ollama and LM Studio add one-command setup and OpenAI-compatible servers on ports 11434 and 1234, and llama-cpp-python embeds the same engine in Python applications.
llama.cpp Reference Implementation
llama.cpp is the reference GGUF runtime, released under the MIT license at no cost. Its tools include llama-cli, llama-server (an OpenAI-compatible HTTP server) and llama-quantize, with options such as --n-gpu-layers and --main-gpu. It supports Linux, macOS, Windows, and mobile targets, with CUDA, Metal, and Vulkan backends among others. Power users compile custom binaries for their CPU and GPU to get the most speed. Setting --n-gpu-layers high enough offloads the whole model to the GPU. llama-quantize converts a GGUF file to a type such as Q4_K_M. --main-gpu selects the primary GPU when several are present. llama.cpp gives the most direct control over quantization of any tool in this list.
Ollama and LM Studio for Everyday Use
Ollama is a free desktop application and REST API that pulls models in one command. It runs on macOS, Windows, and Linux. As of September 2026, running models locally is free, and Ollama also sells paid cloud plans starting at $20 per month, per its pricing page ↗. LM Studio is a free GUI with hardware detection and a built-in local server; it has been free for work use as well since July 2025 ↗. Both tools expose OpenAI-compatible endpoints for script integration. Ollama serves its API on port 11434 by default, including /v1/chat/completions. LM Studio's local server listens on port 1234 by default.
Python Integration with llama-cpp-python
llama-cpp-python wraps the llama.cpp GGUF engine for Python applications. A standard pip install llama-cpp-python builds the library from source, so it needs CMake and a compiler. The package supports GPU offloading through the same backends as the parent project, set with CMAKE_ARGS at install time. Developers embed GGUF inference directly into FastAPI services or Jupyter notebooks. The Llama constructor accepts an n_gpu_layers argument. The package also includes an OpenAI-compatible server.
| Tool | Pricing | Key Features | Limitations | Best Use Case | Platform Support |
|---|
| llama.cpp | Free (MIT) | Full quantization CLI, multi-backend | Mostly CLI | Maximum performance builds | Linux, macOS, Windows, mobile |
| Ollama | Free locally; paid cloud plans | Model pull, OpenAI-compatible API | Reduced low-level control | Quick local servers | macOS, Windows, Linux |
| LM Studio | Free (home and work) | GUI, hardware auto-detect | GUI app is closed source | Non-technical users | Windows, macOS, Linux |
| GPT4All | Free | Curated GGUF catalog, chat UI | Slower update cadence | Offline desktop use | Cross-platform desktop |
| llama-cpp-python | Free | Python bindings to GGUF runtime | Requires build environment | Application embedding | All platforms with Python |
What quantization recommendations exist by hardware in 2026?
Q4_K_M is the usual default for 7B to 8B models on 8 GB VRAM: the llama.cpp quantize README lists Llama 3.1 8B at 4.58 GiB in Q4_K_M and 5.33 GiB in Q5_K_M. CPU-only machines with 32 GB of RAM can run Q5_K_M or Q6_K files for 13B-class models, and Apple Silicon uses the same GGUF files through the Metal backend.
8 GB VRAM Guidance
Systems with 8 GB VRAM commonly load Q4_K_M GGUF files for 7B-8B models. The llama.cpp quantize README lists a Q4_K_M Llama 3.1 8B file at 4.58 GiB, which leaves room for the KV cache at moderate context lengths. Q5_K_M improves quality, and the same model at Q5_K_M is listed at 5.33 GiB, so it is a tighter fit on 8 GB cards. The KV cache grows with context length, so long contexts need more headroom than the file size suggests. 13B-class models at Q4_K_M generally need partial CPU offload on 8 GB cards.
CPU-Only and Apple Silicon Setups
CPU-only machines with 32 GB of system RAM can run Q5_K_M or Q6_K files for 13B-class models. Apple Silicon devices with unified memory use llama.cpp's Metal backend, which is enabled by default on macOS, and the same GGUF files used on NVIDIA cards. Migration from legacy GGML files is easiest by downloading the matching GGUF variant. llama.cpp also ships a convert_llama_ggml_to_gguf.py script for old LLaMA GGML files. GPT4All's catalog lists GGUF models for CPU-only and Apple Silicon downloads.
What benchmarks and migration advice apply for developers in 2026?
No verified 2025 or 2026 benchmark compares GGUF with GGML, because current tools no longer load GGML files. Speed depends on the GPU or CPU, the backend, the quantization type and the context length, so measure with llama-bench on your own hardware. To migrate, download the matching GGUF or convert from the original Hugging Face repository.
Speed depends on the GPU or CPU, the backend (CUDA, Metal, Vulkan), the quantization type, and the context length. The llama.cpp quantize README publishes prompt-processing and generation speeds per quantization type for one reference setup, which is a better starting point than third-party numbers. Ollama and llama-cpp-python both run llama.cpp-based engines, so their speed is usually close to a native llama.cpp build on the same hardware. Measure on your own hardware with llama.cpp's llama-bench tool before choosing a quantization. No independently verified 2025-2026 benchmarks compare GGUF against the retired GGML formats.
Common Pitfalls and Fixes
Users attempting to load GGML files get format errors in current tools. The cleanest fix is to convert from the original Hugging Face repository with the latest llama.cpp convert_hf_to_gguf.py script. Power users prefer direct llama.cpp builds for custom layer offloading that GUI tools do not expose. Developers seeking maximum control compile llama.cpp from source rather than relying on packaged distributions. Step 1: git clone https://github.com/ggml-org/llama.cpp. Step 2: cmake -B build -DGGML_CUDA=ON (Metal is on by default on macOS). Step 3: cmake --build build --config Release. Step 4: ./build/bin/llama-quantize model-f16.gguf model-Q4_K_M.gguf Q4_K_M. Step 5: ./build/bin/llama-cli -m model-Q4_K_M.gguf --n-gpu-layers 99.
For broader open-source model comparisons, see our open-source LLM comparison of Llama, DeepSeek and Qwen. Mac-specific setups follow the same GGUF workflow with the Metal backend.
FAQ
What is GGML and GGUF?
GGML names both the tensor library behind llama.cpp and the early model file format that used it. GGUF is the file format that replaced GGML, GGMF and GGJT in August 2023. The ggml library is still maintained; only the old file format is retired, and current tools load GGUF files only.
What does GGUF mean in AI?
In AI tooling, GGUF is the single-file binary container for models run with llama.cpp and tools built on it. One file holds the metadata, tokenizer and tensor data, using typed key-value metadata so new fields can be added without breaking older files. Hugging Face lists GGUF files on the Hub and shows their metadata.
Compared with the earlier GGML, GGMF and GGJT files, GGUF stores hyperparameters as typed key-value metadata instead of an untyped list, identifies the model architecture, and can gain new fields without breaking compatibility. A Hugging Face checkpoint has to be converted with convert_hf_to_gguf.py before llama.cpp can load it.
Which GGUF quantization should I use for 8 GB VRAM?
Q4_K_M is a common choice for 7B-8B models on 8 GB hardware because it balances quality and memory footprint; a Llama 3.1 8B Q4_K_M file is about 4.6 GiB according to the llama.cpp quantize README.
Does Ollama still support old GGML files?
No. Ollama and other current tools load GGUF; legacy GGML files need to be replaced with GGUF versions.
How do I convert a new model to GGUF?
Use the latest llama.cpp convert_hf_to_gguf.py script, then llama-quantize to produce your preferred quantization level.
Is there any reason to keep GGML files in 2026?
Only for archival purposes. The GGML file format is unsupported by current tools, so migrate to GGUF to avoid compatibility issues.
llama.cpp provides the most control when compiling for specific hardware.
Sources