Open Source AI · 11 min read
Llama 4 Review 2026: Scout, Maverick and What Came Next
Llama 4 (April 2025) reviewed with Muse Spark Open (Oct 2026) as Meta’s current open line. Unverifiable HumanEval tables removed.
Llama 4 (April 2025) reviewed with Muse Spark Open (Oct 2026) as Meta’s current open line. Unverifiable HumanEval tables removed.
Meta released Llama 4 in April 2025 (Scout / Maverick MoE). As of November 5, 2026, Meta’s newer Muse Spark line — including Muse Spark Open (October 15, 2026) — is the current Meta open-weight story. This review keeps Llama 4 facts that Meta published, drops unverifiable score tables, and points you to Muse for new projects.
| Fact | Value | Source | Checked on |
|---|---|---|---|
| Llama 4 announcement | April 2025; MoE Scout and Maverick; Behemoth previewed | Meta Llama 4 blog ↗ | 2026-11-05 |
| Scout context | Meta marketed a 10M-token context window for Scout | Same | 2026-11-05 |
| Maverick scale | Meta describes Maverick as a large MoE (hundreds of billions total parameters class with far fewer active) | Same | 2026-11-05 |
| Muse Spark product | April 8, 2026 — Meta Superintelligence Labs multimodal model on meta.ai | Muse Spark intro ↗ | 2026-11-05 |
| Muse Spark Open | Oct 15, 2026 — 816B total / 42B active; 1M context; public weights | Muse Spark Open ↗ | 2026-11-05 |
Updated 2026-11-05: removed fabricated HumanEval leaderboard rows; added Muse Spark Open; honest “what’s current” framing.
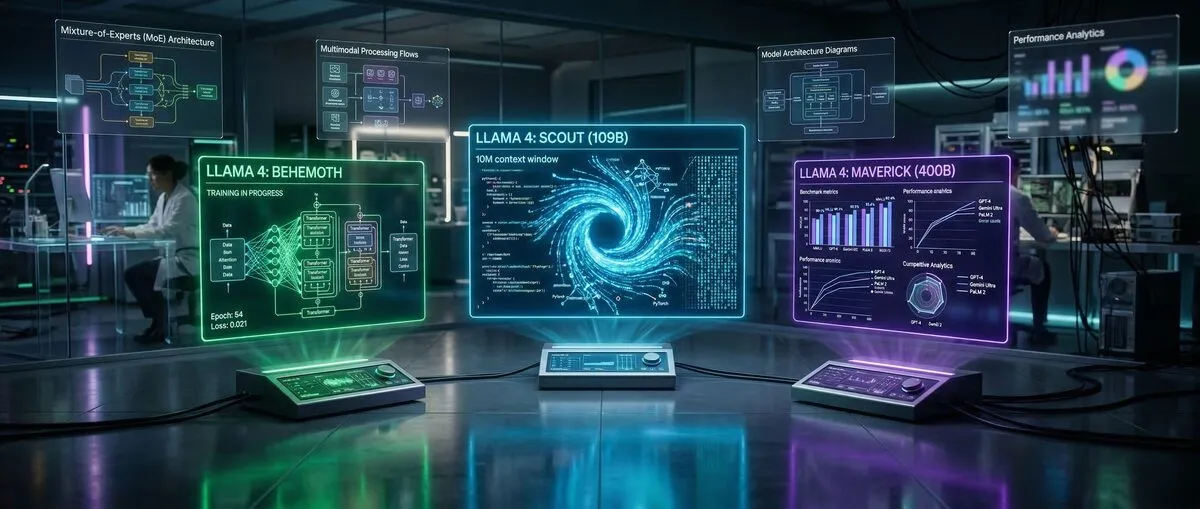
Llama 4 is Meta’s first widely released mixture-of-experts Llama generation after Llama 3.x. Public materials highlight:
Scout — long-context MoE variant (Meta’s 10M-token claim).
Maverick — larger MoE sibling for broader capability.
Behemoth — discussed as a still-larger member; treat availability as whatever Meta’s current download pages list, not as a guaranteed GA product.
Native multimodal “early fusion” messaging and a custom Llama license (not Apache 2.0) apply. Geographic and large-MAU commercial limits in Meta’s license still matter — read the license text before deploying.
Earlier versions of this page asserted exact HumanEval percentages versus “GPT-5.5” / Claude / Gemini and precise $50k–$200k hardware BOMs. Those numbers were not traceable to a primary Meta table we can re-verify today, so they are removed. If you need a benchmark, cite Meta’s blog charts or an independent harness you ran yourself.
Similarly, cloud $/MTok for Llama 4 varies by host. Check Together, Fireworks, Groq, Bedrock, or OpenRouter on the day you buy — we refuse to invent a static price ladder.
| Llama 4 (Apr 2025) | Muse Spark Open (Oct 2026) | |
|---|---|---|
| Role | Previous Meta open generation | Current Meta open-weight flagship pitch |
| Architecture | MoE Llama 4 | MoE multimodal (816B / 42B active) |
| Context (vendor) | Scout up to 10M (claimed) | 1M |
| License | Llama license | Muse Model License |
| When to use | Existing Llama 4 pipelines | New open Meta deployments |
Product Muse Spark (closed API / meta.ai) is separate from Muse Spark Open weights.
Running full-precision Scout/Maverick locally needs multi-GPU servers; most teams use quantized builds (GGUF / FP8) or a host. Exact VRAM depends on quantization and batch size — measure on your stack instead of trusting a blog’s round numbers.
Teams with evals and LoRA adapters already on Scout/Maverick.
Products constrained to the Llama license ecosystem.
Greenfield open Meta work in late 2026 should evaluate Muse Spark Open first, then decide whether Llama 4 still wins on license, tooling, or latency.
Does Llama 4 beat GPT-5.5?
We do not publish an unverified head-to-head. Compare models on your tasks.
Is Behemoth available?
Follow Meta’s current model cards / Hugging Face collections; do not assume GA from 2025 launch prose.
Where next?
Best open-source LLMs 2026 and Muse Spark Open announcement ↗.
A practical introduction to the Model Context Protocol (MCP): how servers, clients and transports work, how to connect common AI tools, and how to build a custom server with the official Python and TypeScript SDKs.

Claude Opus 4.8 costs $5/$25 per million tokens through the API. Kimi K2.6 and MiniMax M3 cost far less per token and each scored 10/10 on a blind debugging test on a 200,000-line codebase.
A comparison of open-weight LLMs from Meta, DeepSeek, Alibaba, Mistral, Google and Microsoft, covering parameters, context length, licenses, vendor-reported benchmarks and fine-tuning options. It also notes the latest releases as of September 2026.
Join builders getting source-cited AI tool analysis. Never sponsored, always attributed.
Source-cited reviews and comparisons of AI tools, published by Rai Ansar.